

Rerankers don’t get talked about much in the GEO world yet. I think they deserve more attention, because they are one of the models involved in deciding whether AI search cites you.
Quick intro if the term is new: when an LLM answers a question, it first retrieves dozens or hundreds of candidate passages from the web. Then a reranker, a smaller model specialized in relevance, reads each passage against the query and scores it. The strongest candidates move on to the LLM writing the answer. It sits between “retrieved” and “cited.”
I was curious how this stage actually behaves, so I ran 12 open-source rerankers on the same two passages.
a preview
Passage A was a solid product description. On-topic, well-written, relevant.
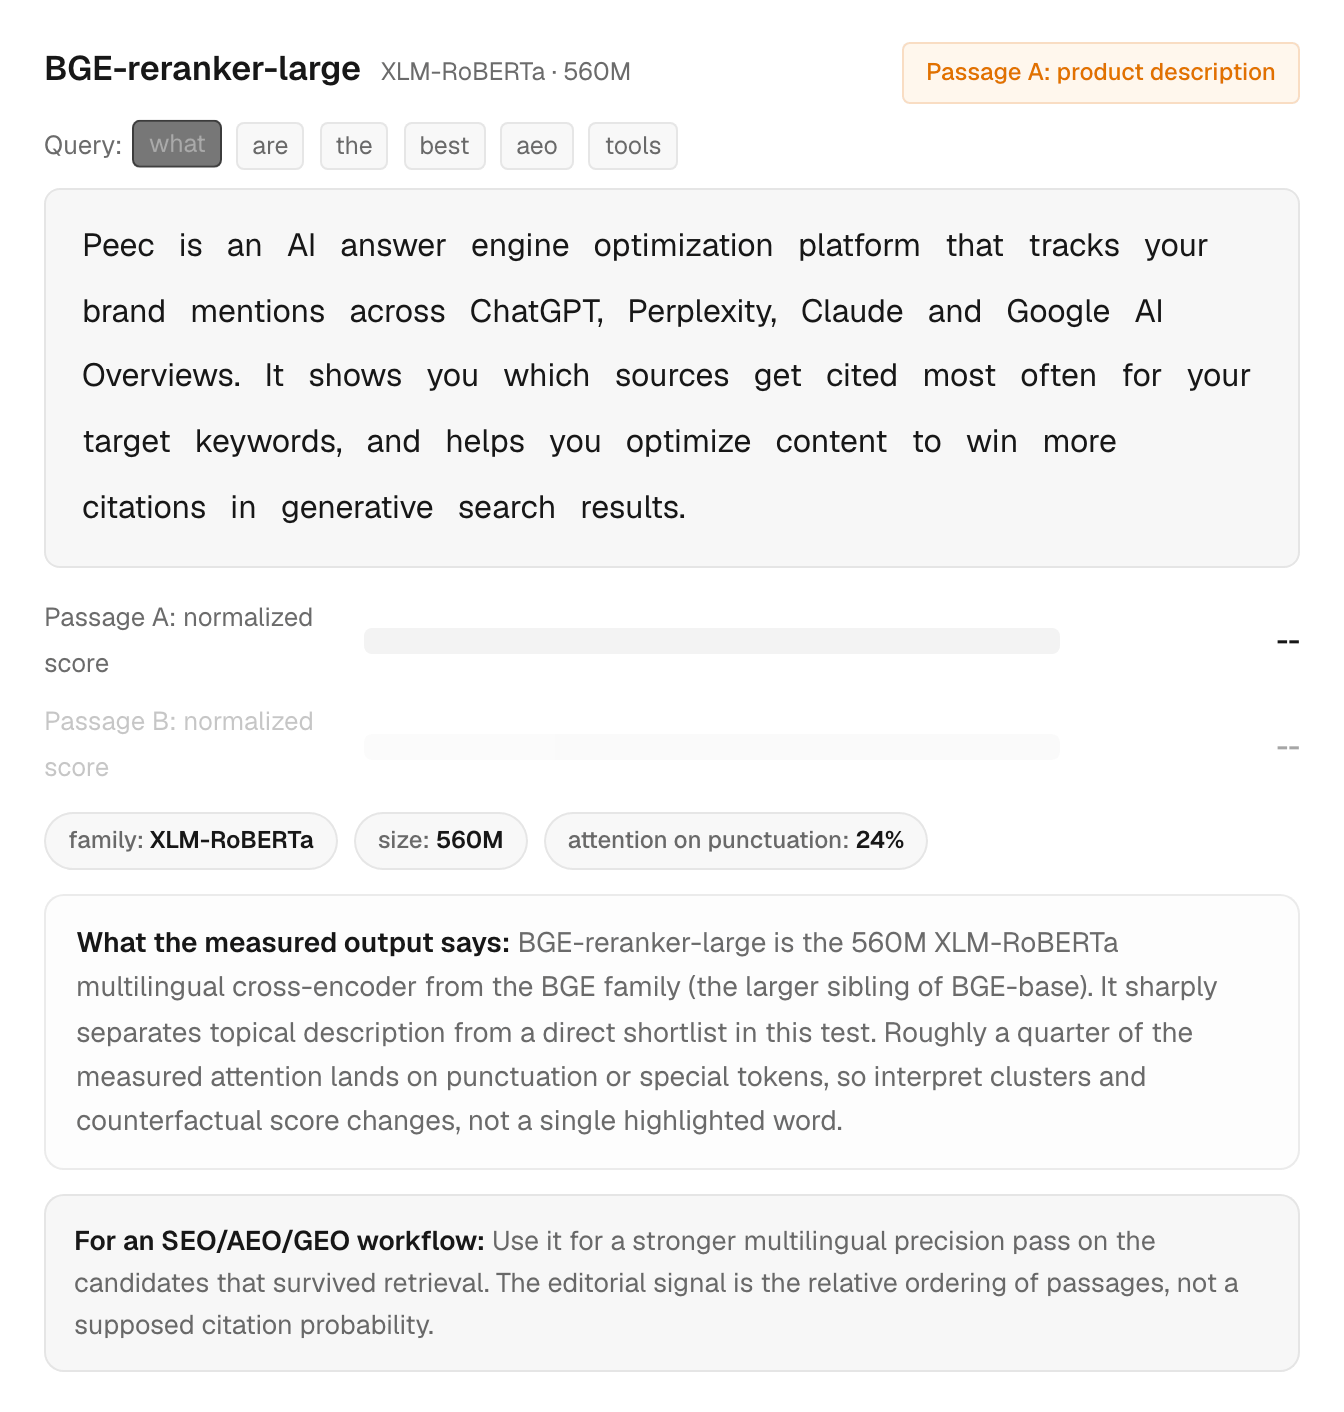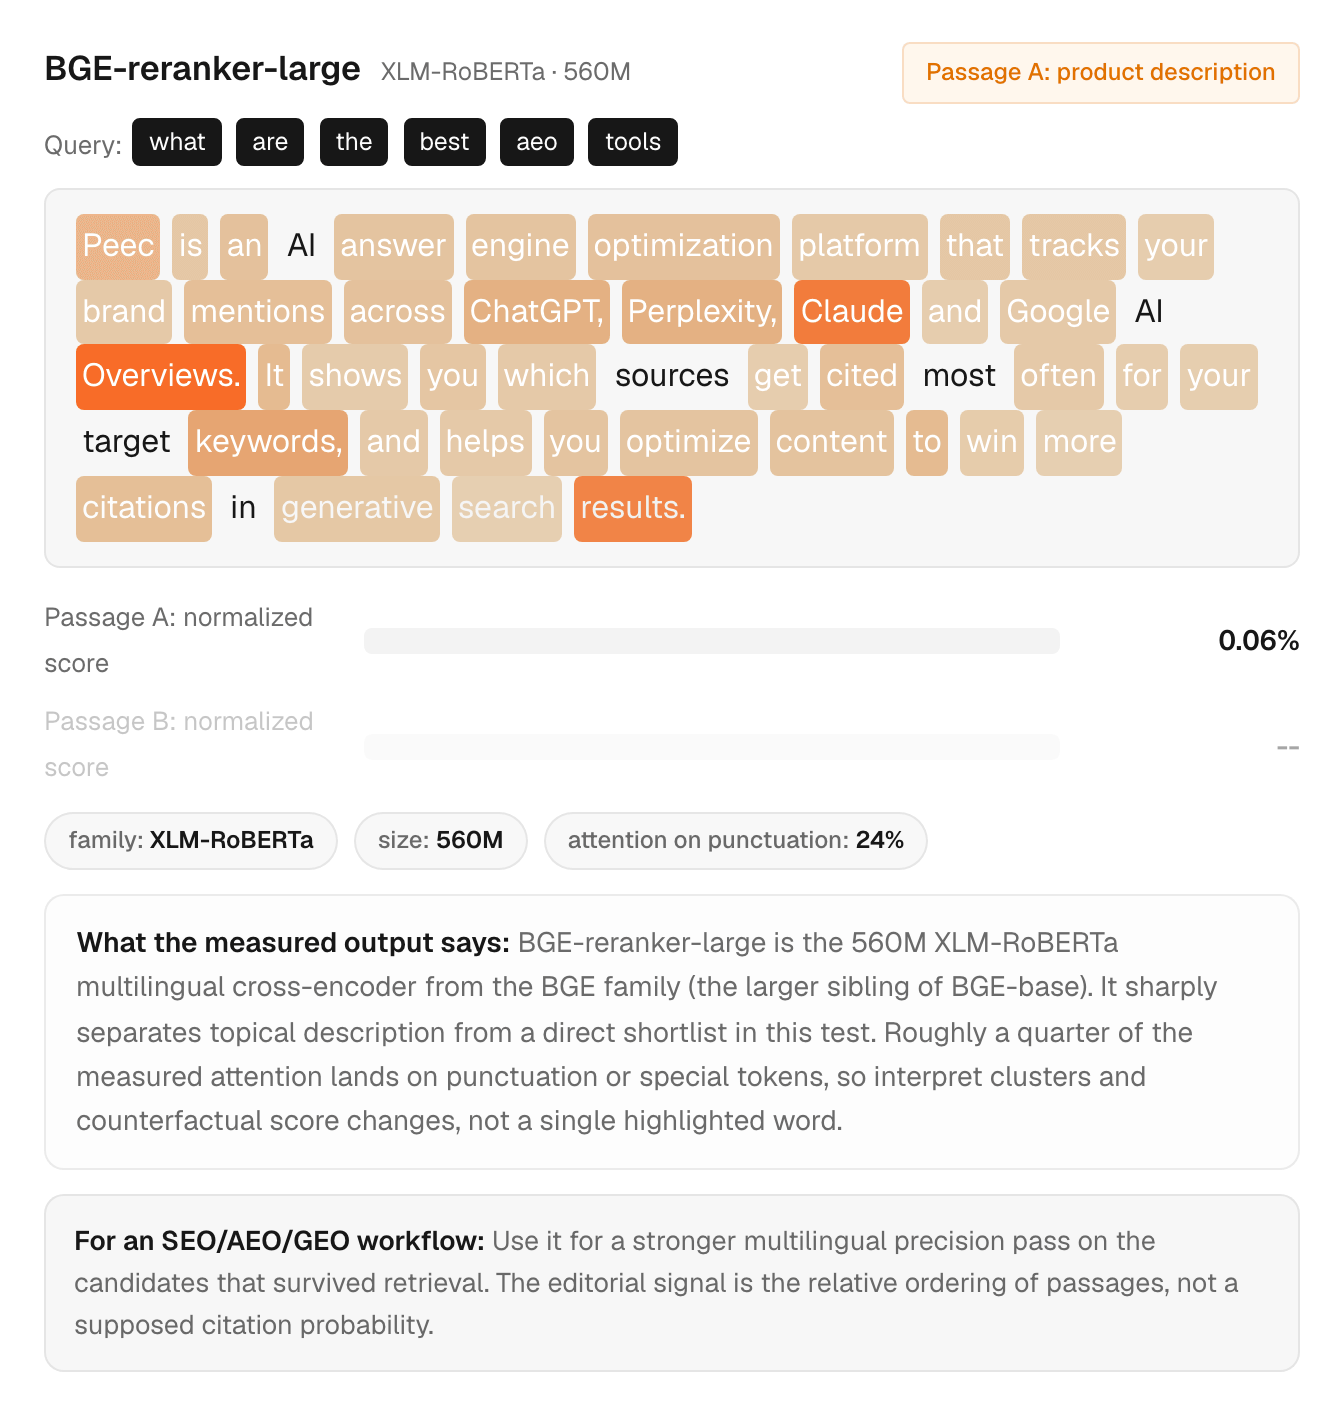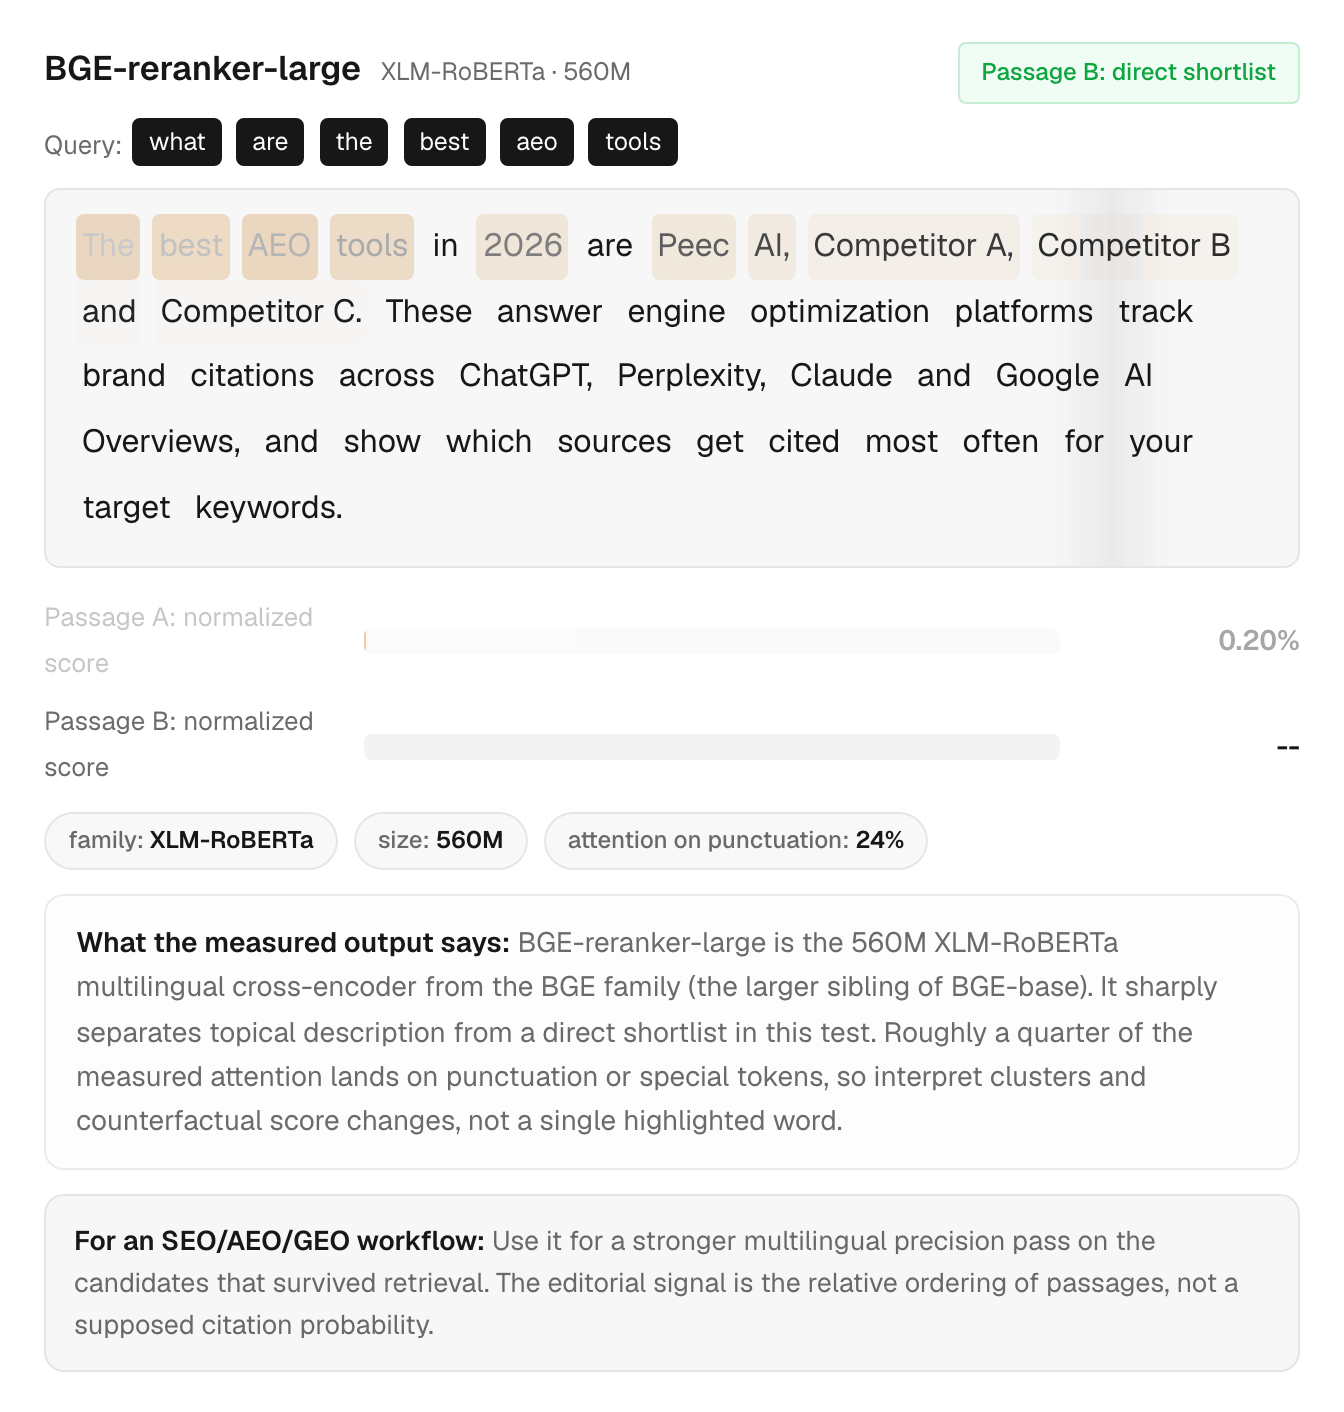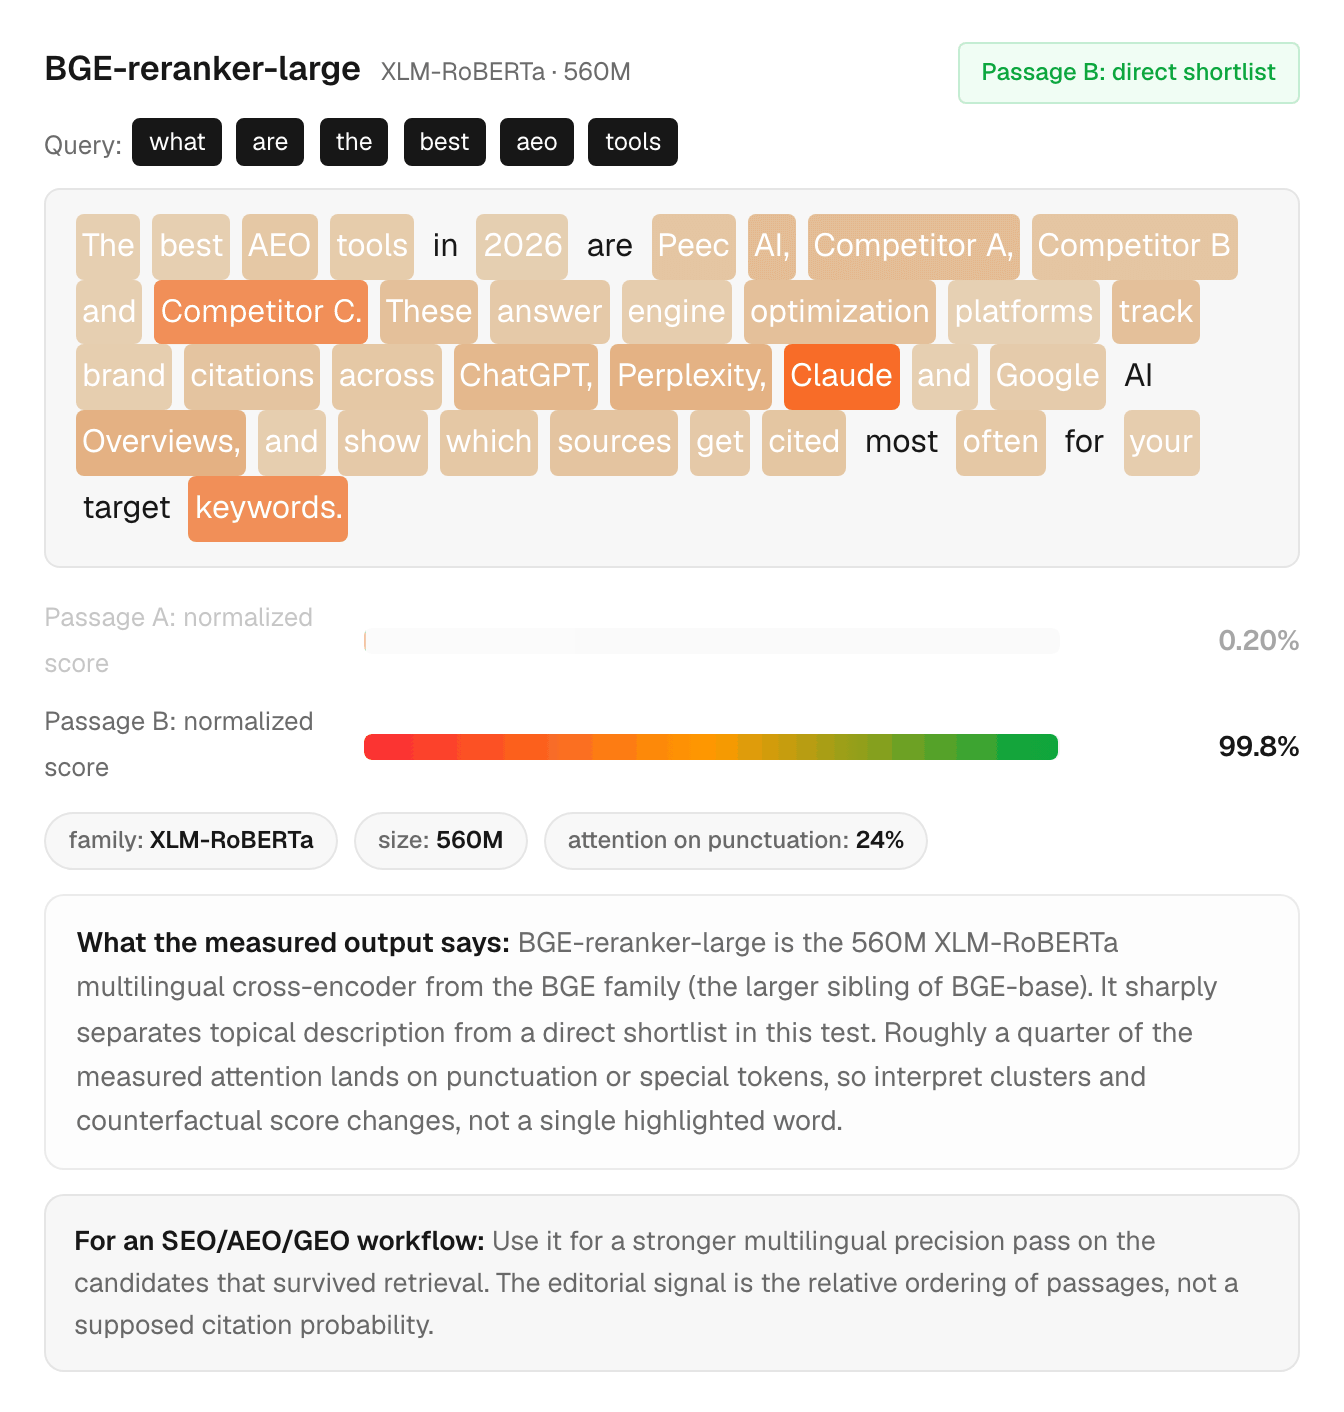
Passage B was one sentence: a direct shortlist answering the query.
The scores surprised me:
MiniLM gave Passage A 0.0019%. Passage B: over 99.9%.
BGE-large: 0.20% vs 99.8%.
Qwen3-Reranker: 0.27% vs 99.9%.
Same topic. Same brand. Very different outcome.
My takeaway: “about the topic” and “answers this query” are two different tests. A lot of good content passes the first and quietly fails the second.
It also helps explain why listicles show up in citations so often. Not because AI loves lists, but because they contain extractable answers, named entities, and coverage for multiple fanout queries. The useful principle is intent-to-answer-shape alignment, not turning everything into a list.
And the simplest edit I found: one direct-answer sentence in the first two lines of the section that targets each query. Not a rewrite. One sentence.
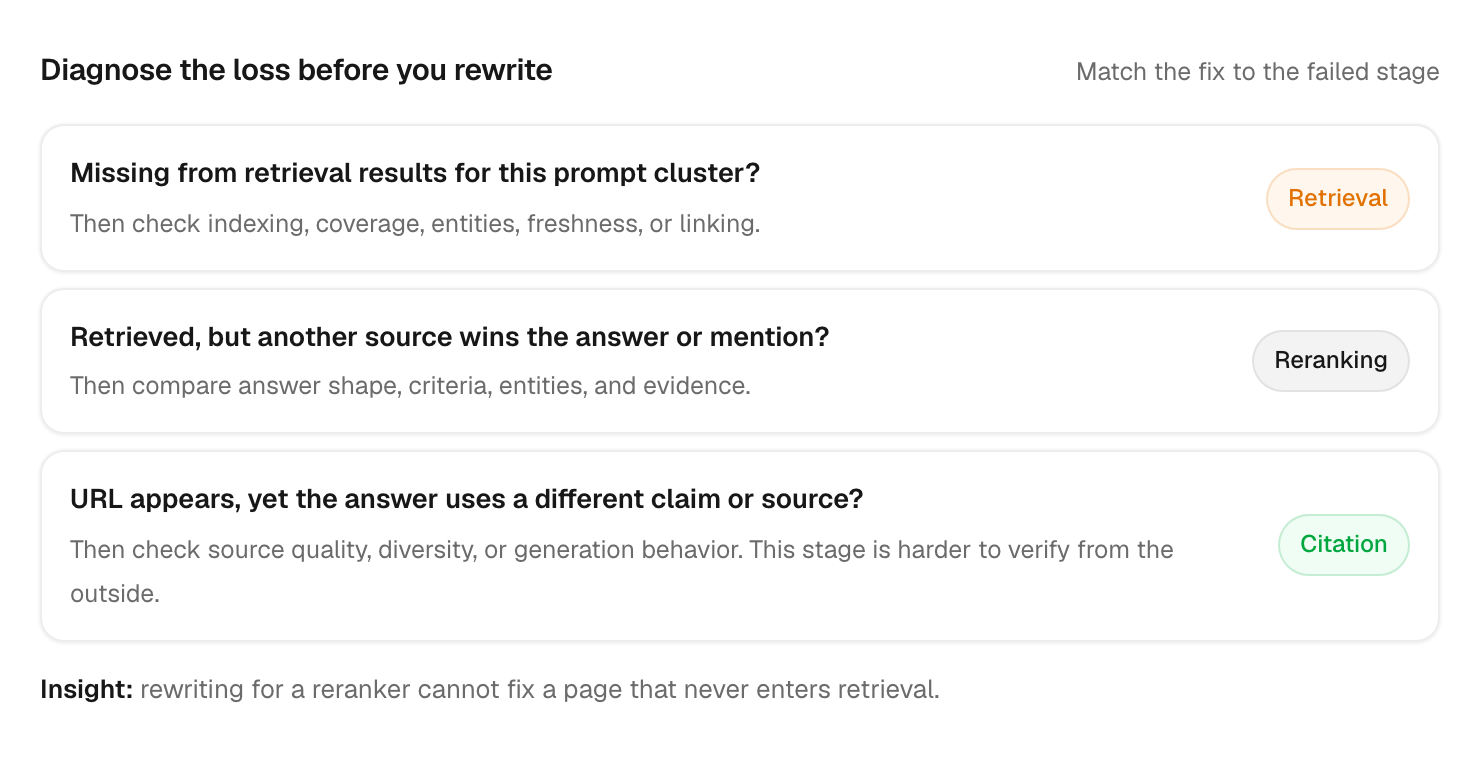
I wrote up the full guide on the Peec AI blog: how BERT-family rerankers work, what SPLADE and ColBERT can tell you about your content, what ChatGPT is probably running, and a “which model when” decision guide for GEO teams.
With animated cards showing each model reading the passages in real time.
More details, a checklist, and more
Link: https://peec.ai/blog/rerankers-for-geo-aeo-how-ai-search-chooses-passages-and-sources
> Every AI search engine works this way
Source?
> 99.9% means citation probability
Disagree
> Put a direct answer in the first two lines
Did you test it side by side putting it in the third and fourth line or the 5th and 6th line for comparison?
The point is you've got some good theories here but I wouldn't stay all of it as proven fact. And you did say probably how chat GPT uses these processes.
Being relevant to the subject and directly answering the query are different things.
Then context comes into play. Previous questions, information about the user that can influence the results or influence which is the best choice.
I love these experiments but factually and reliably tracking brand mentions and citations doesn't really exist yet. Probabilities do. But keep it up it's interesting.